Runs on your server
Open-source models, no license lock-in
Never trained on your data
API servers in the EU and the US
OpenAI and Anthropic compatible
Deploys to physical and air-gapped hardware
The Model Runs on Your Server
-
On your physical hardware
-
When requirements are stricter, the model goes on a server in your building, and if it needs to be fully offline, it runs without any outside connection at all.
-
In your hands after handover
-
Once it’s live, we train your team, hand it over, and stay available for support and upgrades, with nothing about the setup depending on us.
Or Start With Our API
Some teams want the guarantees before they want the hardware. We host open-source models behind an API that works the same way OpenAI’s and Anthropic’s do.
Choose the region
Requests can go to our servers in Europe or the US. You decide where traffic is processed.
Nothing is stored
Your prompts are processed in memory, answered, and gone. That’s what zero retention means in practice.
Keep your existing stack
Your prompts, tooling and existing SDK choices can carry over when you switch the base URL and key.
The Whole Migration
Is
One Line
Point your OpenAI client at our base URL with a new key, or keep your Anthropic client talking to /v1/messages, and the rest of your stack never notices the change.
OpenAI-compatible
client = OpenAI(
base_url=”YOUR_PLATFORM_BASE_URL“,
api_key=”YOUR_API_KEY”
)
response = client.chat…
Anthropic-compatible
client = Anthropic(
base_url=”YOUR_PLATFORM_BASE_URL“,
api_key=”YOUR_API_KEY”
)
endpoint = “/v1/messages”
The Models We Deploy
We can install any open-source model. These are the ones we deploy most often, and what each is best at.
-
Gemma
Google’s open family, and the one we suggest when budgets are tight. Smaller versions handle chat, summarization and everyday text work without serious hardware.
- Budget-friendly
- Everyday text
- Smaller hardware
-

Qwen
Our pick when the work is multilingual or heavy on code. It comes in a wide range of sizes, so there’s usually a version that fits the hardware you already have.
- Multilingual
- Code
- Flexible sizes
-
Mistral & Magistral
Strong European model families. Mistral gets strong performance from modest hardware, while Magistral adds step-by-step reasoning for harder problems.
- EU option
- Efficient
- Reasoning
-

DeepSeek
One of the strongest open options for reasoning, analysis, mathematics and code, with efficient performance for its size.
- Reasoning
- Math
- Code
-

gpt-oss
OpenAI’s open-weight models, suited to teams that already know the ChatGPT interaction style. The smaller version can run on a single GPU.
- Open-weight
- Familiar behavior
- Single GPU option
-
GLM
A strong coder and a practical choice when the model will be writing software or working through multi-step tasks with other tools.
- Software
- Agents
- Multi-step tasks
Closed-Source APIs

Open-Source, Deployed by Us
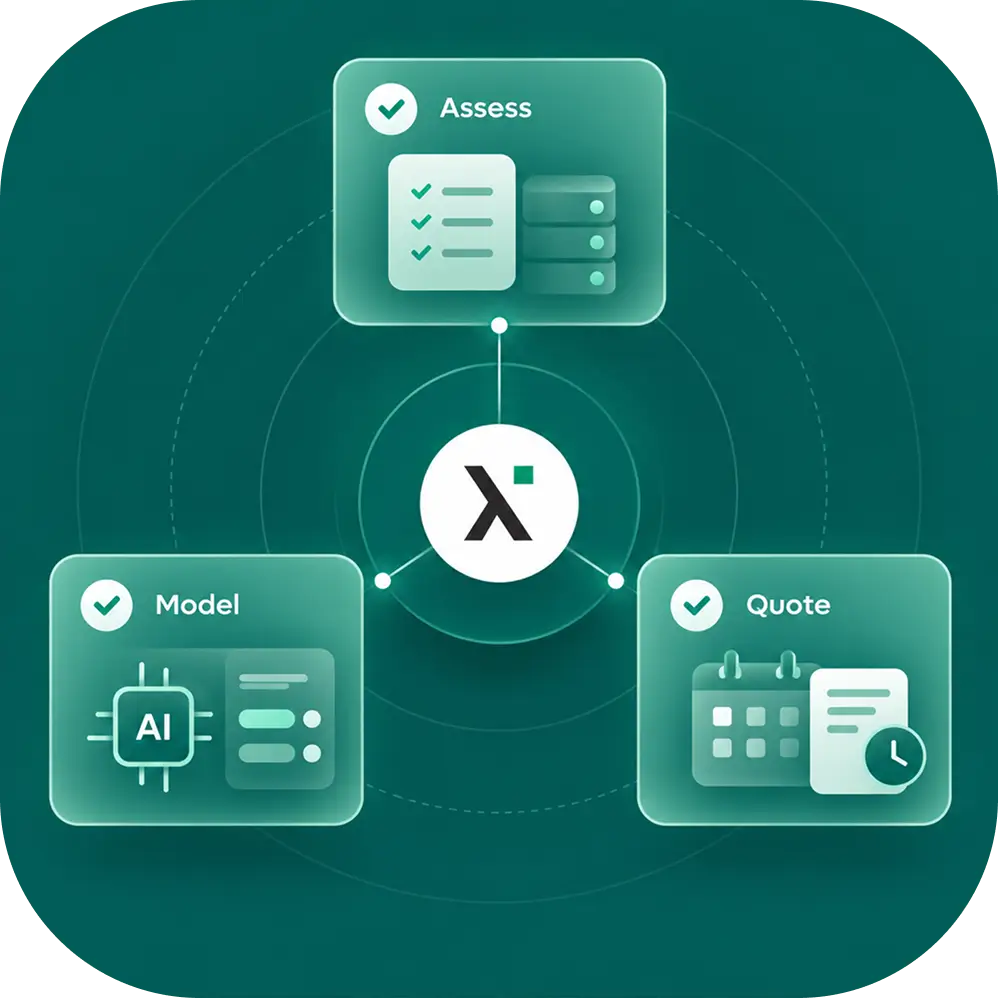
How a Deployment Starts
By the end of the first call you’ll know which model suits your workload, what hardware it needs, and roughly what the project will cost.
-
01
Assess workload + environment
Review what the model needs to do and what infrastructure you already have.
-
02
Recommend the right model
Match capability, hardware requirements and budget to a practical open-source option.
-
03
Fixed quote + timeline
Confirm the project in writing before anything gets installed.
Frequently Asked Questions
-
Which models can we run?
-
Any open-source model your hardware can run, including Gemma, Qwen, Mistral, Magistral, DeepSeek, gpt-oss, and GLM. Tell us the workload and the budget, and we’ll recommend the one we’d use ourselves.
-
Can you deploy on a physical or air-gapped server?
-
Yes. Where your data cannot leave the building, the model goes on hardware inside it with no outside connection, and we’ll give you a real timeline for that rather than a hopeful one.
-
Where do the API servers run?
-
One in Europe and one in the US. Your requests go to the server you choose and nowhere else.
-
What does it cost to get started?
-
The API comes with $10 in free credits and no setup fee, so you can test your real workload today. A deployment starts from $900, quoted as one fixed figure once we’ve seen your environment.